AI-in-the-loop Workflow
This is an example of how Dragon can be used to execute an AI-in-the-loop workflow. Inspiration for this demo comes from the NERSC-10 Workflow Archetypes White Paper. This workflow most closely resembles the workflow scenario given as part of archetype four.
In this example, we use a small model implemented in PyTorch to compute an approximation to \(\sin(x)\).
In parallel, while performing inference with the model, we launch sim-cheap on four MPI ranks.
This MPI job computes the Taylor approximation to \(\sin(x)\) and compares this with the output of the model.
If the difference is less than 0.05 we consider the model’s approximation to be sufficiently accurate and print out the
result with the exact result.
If the difference is greater than 0.05 we consider this a failure and re-train the model on a new set of data.
To generate this data we launch sim-expensive.
This MPI job is launched on eight ranks-per-node and each rank generates 32 data points of the form \((x, \sin(x))\)
where \(x \in U(-\pi, \pi)\).
This data is aggregated into a PyTorch tensor and then used to train the model.
We then re-evaluate the re-trained model and decide if we need to re-train again or if the estimate is sufficiently
accurate. We continue this loop until we’ve had five successes.
Fig. 7 presents the structure of this main loop. It shows when each MPI application is launched and what portions are executed in parallel.
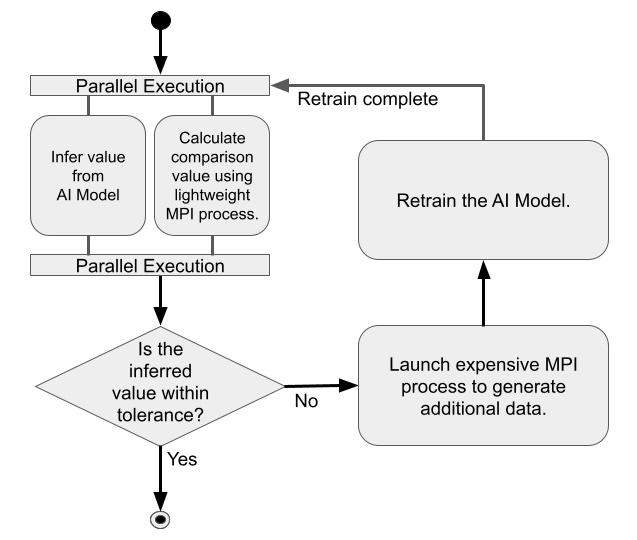
Fig. 7 Example AI-in-the-loop workflow
This example consists of the following python files:
ai-in-the-loop.py- This is the main file. It contains functions for launching both MPI executables and parsing the results as well as imports functions defined inmodel.pyand coordinates the model inference and training with the MPI jobs.model.py- This file defines the model and provides some functions for model training and inference.
Below, we present the main Python code ai-in-the-loop.py, which acts as the coordinator of the workflow. The code of the other files can be found in ai-in-the-loop.
  1import dragon
  2import multiprocessing as mp
  3
  4import os
  5import math
  6import torch
  7from itertools import count
  8from model import Net, make_features, infer, train
  9
 10from dragon import ProcessTemplate, ProcessGroup, System
 11from dragon.native.process import Process, Popen
 12from dragon.infrastructure.connection import Connection
 13from dragon.infrastructure.facts import PMIBackend
 14
 15
 16def parse_results(stdout_conn: Connection) -> tuple:
 17    """Read stdout from the Dragon connection.
 18
 19    :param stdout_conn: Dragon connection to rank 0's stdout
 20    :type stdout_conn: Connection
 21    :return: tuple with a list of x values and the corresponding sin(x) values.
 22    :rtype: tuple
 23    """
 24    x = []
 25    y = []
 26    output = ""
 27    try:
 28        # this is brute force
 29        while True:
 30            output += stdout_conn.recv()
 31    except EOFError:
 32        pass
 33    finally:
 34        stdout_conn.close()
 35
 36    split_line = output.split("\n")
 37    for line in split_line[:-1]:
 38        try:
 39            x_val = float(line.split(",")[0])
 40            y_val = float(line.split(",")[1])
 41            x.append(x_val)
 42            y.append(y_val)
 43        except (IndexError, ValueError):
 44            pass
 45
 46    return x, y
 47
 48
 49def generate_data(num_ranks: int, samples_per_rank: int, sample_range: list, number_of_times_trained: int) -> tuple:
 50    """Launches mpi application that generates (x, sin(x)) pairs uniformly sampled from [sample_range[0], sample_range[1]).
 51
 52    :param num_ranks: number of ranks to use to generate data
 53    :type num_ranks: int
 54    :param samples_per_rank: number of samples to generate per rank
 55    :type samples_per_rank: int
 56    :param sample_range: range from which to sample training data
 57    :type sample_range: list
 58    :param number_of_times_trained: number of times trained. can be used to set a seed for the mpi application.
 59    :type number_of_times_trained: int
 60    :return: tuple of PyTorch tensors containing data and targets respectively
 61    :rtype: tuple
 62    """
 63    """Launch process group and parse data"""
 64    exe = os.path.join(os.getcwd(), "sim-expensive")
 65    args = [str(samples_per_rank), str(sample_range[0]), str(sample_range[1]), str(number_of_times_trained)]
 66    run_dir = os.getcwd()
 67
 68    grp = ProcessGroup(restart=False, pmi=PMIBackend.CRAY)
 69
 70    # Pipe the stdout output from the head process to a Dragon connection
 71    grp.add_process(nproc=1, template=ProcessTemplate(target=exe, args=args, cwd=run_dir, stdout=Popen.PIPE))
 72
 73    # All other ranks should have their output go to DEVNULL
 74    grp.add_process(
 75        nproc=num_ranks - 1, template=ProcessTemplate(target=exe, args=args, cwd=run_dir, stdout=Popen.DEVNULL)
 76    )
 77    # start the process group
 78    grp.init()
 79    grp.start()
 80    group_procs = [Process(None, ident=puid) for puid in grp.puids]
 81    for proc in group_procs:
 82        if proc.stdout_conn:
 83            # get info printed to stdout from rank 0
 84            x, y = parse_results(proc.stdout_conn)
 85    # wait for workers to finish and shutdown process group
 86    grp.join()
 87    grp.stop()
 88    grp.close()
 89    # transform data into tensors for training
 90    data = torch.tensor(x)
 91    target = torch.tensor(y)
 92    return data, target.unsqueeze(1)
 93
 94
 95def compute_cheap_approx(num_ranks: int, x: float) -> float:
 96    """Launch process group with cheap approximation and parse output to float as a string
 97
 98    :param num_ranks: number of mpi ranks (and therefor terms) to use for the cheap approximation
 99    :type num_ranks: int
100    :param x: point where you are trying to compute sin(x)
101    :type x: float
102    :return: taylor expansion of sin(x)
103    :rtype: float
104    """
105    exe = os.path.join(os.getcwd(), "sim-cheap")
106    args = [str(x)]
107    run_dir = os.getcwd()
108
109    grp = ProcessGroup(restart=False, pmi=PMIBackend.CRAY)
110
111    # Pipe the stdout output from the head process to a Dragon connection
112    grp.add_process(nproc=1, template=ProcessTemplate(target=exe, args=args, cwd=run_dir, stdout=Popen.PIPE))
113
114    # All other ranks should have their output go to DEVNULL
115    grp.add_process(
116        nproc=num_ranks - 1, template=ProcessTemplate(target=exe, args=args, cwd=run_dir, stdout=Popen.DEVNULL)
117    )
118    # start the process group
119    grp.init()
120    grp.start()
121    group_procs = [Process(None, ident=puid) for puid in grp.puids]
122    for proc in group_procs:
123        # get info printed to stdout from rank 0
124        if proc.stdout_conn:
125            _, y = parse_results(proc.stdout_conn)
126    # wait for workers to finish and shutdown process group
127    grp.join()
128    grp.stop()
129    grp.close()
130
131    return y
132
133
134def infer_and_compare(model: torch.nn, x: float) -> tuple:
135    """Launch inference and cheap approximation and check the difference between them
136
137    :param model: PyTorch model that approximates sin(x)
138    :type model: torch.nn
139    :param x: value where we want to evaluate sin(x)
140    :type x: float
141    :return: the model's output val and the difference between it and the cheap approximation value
142    :rtype: tuple
143    """
144    with torch.no_grad():
145        # queues to send data to and from inference process
146        q_in = mp.Queue()
147        q_out = mp.Queue()
148        q_in.put((model, x))
149        inf_proc = mp.Process(target=infer, args=(q_in, q_out))
150        inf_proc.start()
151        # launch mpi application to compute cheap approximation
152        te_fx = compute_cheap_approx(4, x.numpy()[0])
153        inf_proc.join()
154        model_val = q_out.get()
155        # compare cheap approximation and model value
156        diff = abs(model_val.numpy() - te_fx[0])
157
158    return model_val, diff
159
160
161def main():
162    ranks_per_node = 8
163    data_interval = [-math.pi, math.pi]
164    samples_per_rank = 32
165    my_alloc = System()
166    # Define model
167    model = Net()
168    # Define optimizer
169    optimizer = torch.optim.Adam(model.parameters(), lr=0.01)
170    # Load pretrained model
171    PATH = "model_pretrained_poly.pt"
172    checkpoint = torch.load(PATH)
173    model.load_state_dict(checkpoint["model_state_dict"])
174    optimizer.load_state_dict(checkpoint["optimizer_state_dict"])
175
176    number_of_times_trained = 0
177    successes = 0
178
179    generate_new_x = True
180
181    while successes < 5:
182        if generate_new_x:
183            # uniformly sample from [-pi, pi)
184            x = torch.rand(1) * (2 * math.pi) - math.pi
185
186        model_val, diff = infer_and_compare(model, x)
187        if diff > 0.05:
188            print(f"training", flush=True)
189            # want to train and then retry same value
190            generate_new_x = False
191            number_of_times_trained += 1
192            # interval we uniformly sample training data from
193            # launch mpi job to generate data
194            data, target = generate_data(
195                my_alloc.nnodes * ranks_per_node, samples_per_rank, data_interval, number_of_times_trained
196            )
197            # train model
198            loss = train(model, optimizer, data, target)
199        else:
200            successes += 1
201            generate_new_x = True
202            print(f" approx = {model_val}, exact = {math.sin(x)}", flush=True)
203
204
205if __name__ == "__main__":
206    mp.set_start_method("dragon")
207    main()
Installation
After installing dragon, the only other dependency is on PyTorch. The PyTorch version and corresponding pip command can be found here (https://pytorch.org/get-started/locally/).
pip install torch torchvision torchaudio
Description of the system used
For this example, HPE Cray Hotlum nodes were used. Each node has AMD EPYC 7763 64-core CPUs.
How to run
Example Output when run on 16 nodes with 8 MPI ranks-per-node used to generate data and four MPI ranks to compute the cheap approximation
 1> make
 2gcc -g  -pedantic -Wall -I /opt/cray/pe/mpich/8.1.26/ofi/gnu/9.1/include -L /opt/cray/pe/mpich/8.1.26/ofi/gnu/9.1/lib   -c -o sim-cheap.o sim-cheap.c
 3gcc -g  -pedantic -Wall -I /opt/cray/pe/mpich/8.1.26/ofi/gnu/9.1/include -L /opt/cray/pe/mpich/8.1.26/ofi/gnu/9.1/lib  sim-cheap.o -o sim-cheap -lm -L /opt/cray/pe/mpich/8.1.26/ofi/gnu/9.1/lib -lmpich
 4gcc -g  -pedantic -Wall -I /opt/cray/pe/mpich/8.1.26/ofi/gnu/9.1/include -L /opt/cray/pe/mpich/8.1.26/ofi/gnu/9.1/lib   -c -o sim-expensive.o
 5gcc -g  -pedantic -Wall -I /opt/cray/pe/mpich/8.1.26/ofi/gnu/9.1/include -L /opt/cray/pe/mpich/8.1.26/ofi/gnu/9.1/lib  sim-expensive.o -o sim-expensive -lm -L /opt/cray/pe/mpich/8.1.26/ofi/gnu/9.1/lib -lmpich
 6> salloc --nodes=16 --exclusive
 7> dragon ai-in-the-loop.py
 8training
 9approx = 0.1283823400735855, exact = 0.15357911534767393
10training
11approx = -0.41591891646385193, exact = -0.4533079140996079
12approx = -0.9724616408348083, exact = -0.9808886564963794
13approx = -0.38959139585494995, exact = -0.4315753703483373
14approx = 0.8678910732269287, exact = 0.8812041533601648